bestweb345
  • Home
  • Decorate
  • Gardening
  • House Tours
  • DIY Projects
  • Expert Advice
  • More
bestweb345
  • Home
  • Decorate
  • Gardening
  • House Tours
  • DIY Projects
  • Expert Advice
  • More
bestweb345
bestweb345
  • Home
  • Decorate
  • Gardening
  • House Tours
  • DIY Projects
  • Expert Advice
  • More

@2022 - All Right Reserved. Designed and Developed by PenciDesign

Tech

How Small Procurement Fixes Can Transform a Led Display Manufacturer’s Results

by Jessica May 7, 2026
written by Jessica

When a single tweak exposes larger flaws

I remember the afternoon in June 2019 on a rooftop job in Lisbon where a 2.5mm pixel pitch outdoor billboard kept flickering during a festival — and the client lost nearly 12 hours of prime display time; can a single procurement tweak prevent that? Led Display Company taught me early on that most problems start before the factory floor. As a consultant with over 15 years in B2B supply chain and wholesale buying, I often see procurement specs that ignore driver IC variations and refresh rate mismatches; Led Display Manufacturer relationships crumble when these details are left vague.

What exactly breaks?

It isn’t the LED module itself that usually fails first — it’s the mismatch: wrong brightness curves, incompatible driver ICs, or cabinets that don’t breathe (no fuss). I once recommended switching a standard cabinet vent to a simple louver design for a seaside installation in Porto; downtime dropped by 30% in three months. That kind of specific action makes the difference between a silent display and repeated service calls. I’ll walk you through where buyers trip up and what to fix next.

— Moving on to solutions below.

From fixing the old script to choosing the right specs

Here’s a blunt claim: most wholesale buyers overpay for complexity and under-invest in clear specs. I’ve seen tens of purchase orders that list only “outdoor LED screen” and nothing about pixel pitch, ingress protection, or calibration needs; that costs money — real money. Start by demanding concrete test reports (binning details, refresh rate proof) and a maintenance-friendly cabinet layout. When I led a rollout in Madrid in March 2021, standardizing on 3.9mm modules and specifying a minimum 3,840Hz refresh rate cut visual complaints by half within weeks.

What’s Next?

I want you to compare offers not by brand name but by three real metrics — lifetime mean time between failures (MTBF), on-site swap time for an LED module, and verified refresh rate under load. Those are the things that predict uptime. Also, insist on swap-friendly driver ICs and clear warranty clauses about pixel classification; otherwise you inherit someone else’s ambiguity. That’s practical. That’s honest — and it saves you service headaches.

To close: use these three evaluation metrics when vetting vendors — 1) MTBF and documented field cases, 2) Average swap time for modules and cabinet accessibility, 3) Confirmed refresh rate and driver IC compatibility under real conditions. I’ve applied this checklist across projects from small indoor retail screens to large outdoor façades, and it consistently separates suppliers who deliver from those who sell hope. Check supplier claims; test a real unit; and yes — visit an installation in person once (you’ll learn more than a thousand spec sheets). Chainzone
May 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Performance Breakthroughs: Fixing the Flaws in Liquid-Cooled Motor Supply for Wholesale Buyers

by Cynthia May 6, 2026
written by Cynthia

Problem-driven diagnosis — where the real headaches start

I was hauling a pile of 500W mid-drive units up the stairs of a tiny workshop in Auckland when the design problems became painfully obvious; installers were swearing, batteries were getting hot, and orders were delayed. In one quick test (March 2024) a prototype from an ebike supplier hit 85°C after a 20-minute climb — scenario, data, question: that continuous run caused a 30% power derate, so how do we stop losing ride time and warranty claims?

I’m speaking from over 15 years in EV motor supply and consultancy to wholesale buyers, and I keep seeing the same traditional flaws in so-called cooling fixes. The common stops—thicker heatsinks, larger fans, or crude oil-sump ideas—don’t address the core: poor thermal management at the stator-winding interface and mismatched power density expectations. Torque feels impressive on paper, but under load the winding temps spike, the cooling jacket can’t keep pace, and RPM control suffers. It’s annoying as, and costly (we once had to replace 120 motors after a single hill test — true story).

Where designs usually go wrong?

Design teams often optimise for peak torque or peak efficiency and forget continuous duty cycles. That leads to undersized heat exchangers, weak coolant paths, and glue that softens at the wrong temperature. The result: short bursts of great performance, then sudden power clipping. I’ve measured repeat failures where a claimed 2 kW continuous rating fell to 1.4 kW after ten minutes of climbing — not just a spec issue, it’s a real operational failure for fleet buyers.

That’s the mess. Next — how we stop paying for it.

Forward-looking fixes and what wholesale buyers should demand

Technically speaking, the smart move is to treat the liquid-cooled motor as a system, not a part. I now push suppliers to validate thermal paths with real-world profiles (urban stop-start, hill climbs, 30°C ambient) rather than bench bursts. In trials with a reliable ebike supplier in late 2023, swapping to a redesigned cooling jacket and optimised stator winding layout cut peak winding temperature by 25°C and raised continuous output by about 22% — measurable, not marketing fluff. We used torque sensors, inline thermocouples, and repeat endurance cycles to prove it (no guesswork).

Now, let me be blunt: you want repeatability. Ask for thermal maps, not just ratings. Demand to see heat exchanger sizing, coolant flow rates, and expected power density under defined ambient conditions. I recommend you insist on real verification — endurance runs of at least 2 hours at target load — because short bursts hide chronic issues. Also, don’t ignore serviceability; modular cooling lines and accessible seals save big on downtime. Sweet as, right?

What’s Next for procurement?

We need better metrics at the procurement table. I suggest three clear evaluation points to make your next buy count: 1) Continuous power validation — ask for a 2-hour duty cycle report showing sustained output and max winding temp; 2) Thermal-path proof — require CAD cross-sections of coolant channels and measured coolant flow/pressure; 3) Mean time between failure (MTBF) under defined load and ambient (give a date; for example, factory tests completed March 2024). These are simple. They filter vendors who just spray-paint specs into brochures.

I’ll wrap this up with practical advice: treat thermal management as the primary reliability lever — not an afterthought. Check the numbers, demand verified tests, and remember that marginal gains in cooling lead to big savings on warranty and downtime. LUYUAN

May 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Global Trade

How I Quieted Price-Sheet Chaos with a Hanshow Nebular Pro Approach

by William May 6, 2026
written by William

When Labels Break: a frontline account

I once walked into a crowded Hanoi supermarket where paper tags were taped over each other and staff were chasing price mismatches at checkout — that scene (ugh, you know) cost the store both time and trust. Early on I recommended a digital price tag display rollout to cut those manual errors; Hanshow nebular pro became the system we installed. Scenario: shelves lined with hundreds of SKUs; data: 2,000 ESL units deployed in March 2023 that cut labeling errors by 73%; question: why do so many retailers still accept slow, error-prone labeling when a clear ROI appears in six weeks? I say this from over 15 years working B2B supply chain and retail rollouts — I’ve seen similar frustration in Ho Chi Minh City and Singapore, not just Hanoi. I also recall installing Nebular Pro modules next to the store’s POS and seeing OTA updates push prices in under three minutes — that speed changed evening restock routines. The deeper problem is not the tech itself; it’s the legacy processes (manual overrides, paper backup habits) that keep teams stuck. This is important — because fixing process beats buying gadgets every time. Transitioning now to what that fix looks like next.

Hanshow nebular pro

Why traditional solutions fall short — and what a better stack needs

Let me be blunt: old electronic shelf label pilots often die because integrators treat ESL as a gadget, not a node in the retail data plane. Technically, an ESL needs reliable IoT connectivity, solid cloud integration, and clear SKU mapping to the POS — missing any of these and sync fails. I call out three common flaws I routinely see: 1) patchy network planning (Wi‑Fi islands that drop packets), 2) brittle integration (manual CSV price pushes once daily), and 3) no rollback plan for failed OTA updates. I remember a December 2022 launch where nightly CSV pushes overwrote promotional prices and cost a wholesale buyer account about $18,400 in lost margin over five days — painful and preventable. A resilient setup uses MQTT-like messaging or secure API calls, maintains a live SKU registry, and logs every change so you can audit (and reverse) quickly. Also — and this matters — the display medium (e-paper vs LCD) defines update frequency and power budgeting; e-paper gave us a month of battery life with dense price changes, which made maintenance predictable. From my standpoint, digital price systems must be evaluated on three technical criteria: update latency, inventory link fidelity, and error recovery time. Those are measurable. Short story: if you treat digital tags as separate islands, they will fail like islands; if you bind them into the POS/ERP via durable APIs, they become part of daily operations.

Hanshow nebular pro

What’s Next?

Now I switch tone and get a bit technical: a practical architecture for reliable tagging starts with edge gateways, secure cloud synchronization, and deterministic OTA flows. The edge gateway handles local retries and mesh coordination; the cloud keeps canonical prices and pushes diffs; the ESL devices receive diffs and apply them (with checksum verification). When I led a pilot in a 12-store chain in April 2024, we used this architecture and reduced update retries by 86% — that saved technicians a week of truck rolls per month. Implementing a digital price tag display successfully means planning for failure: test rollback, measure battery drain after a promotional blitz, and log every price assignment against a single SKU master. Real-world constraints — store layout, rack density, peak-hour foot traffic — shape your radio plan. I still insist on on-site radio tests; remote planning only gets you so far. Brief interruption — two glitches happened during one rollout—fixed within hours. Then smooth sailing. The future favors systems designed for operational reality, not demo floors.

Final thoughts — metrics to judge the change

I’ll be concise and practical: evaluate any solution (and yes, I include Hanshow nebular pro in my comparisons) by three metrics — update latency (seconds to minutes), reconciliation accuracy (mismatches per 10,000 SKUs), and maintenance load (hours per week per store). I recommend running a two-week live pilot in a busy store and measure those numbers. I’ve led such pilots; they reveal hidden costs fast. In closing, I’ve seen technology transform hourly tasks into predictable workflows, and I believe the right digital price approach does the same for wholesale buyers. (Trust me, I’ve lived the late-night price hunts.) Visit Hanshow.

May 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Navigating RF Swarms and Smart Spectrum: Comparative Insights for Night Ops Hardware

by Frank May 3, 2026
written by Frank

Quick comparison that actually helps

Think of two teams arguing over the same radio channel at 0300: one uses rules and a schedule, the other listens and adapts. That metaphor frames why a military drone manufacturer must weigh static spectrum allocation against cognitive radio strategies when integrating comms into night vision systems. The choice affects UAV link reliability, RF interference resilience, and how well onboard sensors share bandwidth during dense ISR missions.

Cognitive radio vs. dynamic spectrum allocation — the nutshell

Cognitive radio: devices sense spectrum use and pick gaps in real time. Dynamic spectrum allocation (DSA): a managed plan that allocates bands based on priority and policy. Cognitive radio shines where the environment is unpredictable — urban canyons or contested zones with active jamming. DSA wins when command wants predictable behavior and clear priority flows for voice, telemetry, and video. Both approaches touch on spectrum allocation and electromagnetic control; both must coexist with EW considerations.

How this impacts night vision goggles and drone links

Night ops gear increasingly bundles sensors, comms and processing. That means more radios, denser spectrum use, and tougher thermal and power constraints. A few practical trade-offs to consider:

– Latency: adaptive radios add processing overhead, which can hurt low-latency video feeds from an ISR payload.

– Power: sensing and frequency-hopping drain battery life on helmet-mounted units and lightweight UAVs.

– Interoperability: standardized DSA policies simplify coalition ops, especially during joint missions like those NATO ran in Afghanistan — where predictable channels reduced friendly congestion and improved coordination.

Design patterns for manufacturers and integrators

From a product view, the sweet spot is hybrid. Use DSA for baseband planning and policy enforcement, then allow cognitive overlays where ad hoc avoidance is essential. That yields a controlled framework with tactical flexibility. Practical steps:

– Implement priority classes for telemetry, command, and video.

– Build a low-power sensing mode for helmet-mounted radios to limit thermal impact.

– Test EW scenarios in lab and field; simulated jamming uncovers hidden failure modes.

Common mistakes and smarter alternatives

Teams often assume adaptive equals better — that’s a trap. Overzealous frequency hopping can create more collisions in crowded bands. Conversely, rigid DSA schemes can bottleneck during unexpected surges. Smarter alternatives include:

– Policy-driven hybrids that switch modes based on mission phase.

– Modular firmware that lets a drone swap radio stacks — useful for companies like a modern drone company military balancing ISR payloads and comms roles.

– Regular spectrum audits and coordination with local authorities to prevent civilian interference — because legal headaches are worse than a lost link.

Implementation checklist — what to measure

Field trials should track three concrete metrics: packet loss under interference, end-to-end latency for video feeds, and time-to-recover after a jam. Collect baseline numbers in controlled settings, then stress-test with EW scenarios. Doing so reveals whether cognitive layers add value or just complexity.

Advisory: three golden rules for choosing the right approach

1) Prioritize mission-critical flows. If command and control must never drop, assign them fixed, protected lanes via DSA.

2) Reserve cognitive tactics for contested or unpredictable theaters where sensing reduces collisions and improves survivability.

3) Measure power and thermal impact first. If a radio design torpedoes helmet runtime or UAV endurance, its sophistication is irrelevant.

These rules reflect practical trade-offs and the measurable outcomes teams should expect — lower packet loss, clearer priority handling, and longer mission uptime when implemented correctly. The net result: better field performance and fewer surprises on night sorties — and yes, that reliability is why platforms and buyers trust sources like Military Hub. —

May 3, 2026 0 comments
0 FacebookTwitterPinterestEmail
Global Trade

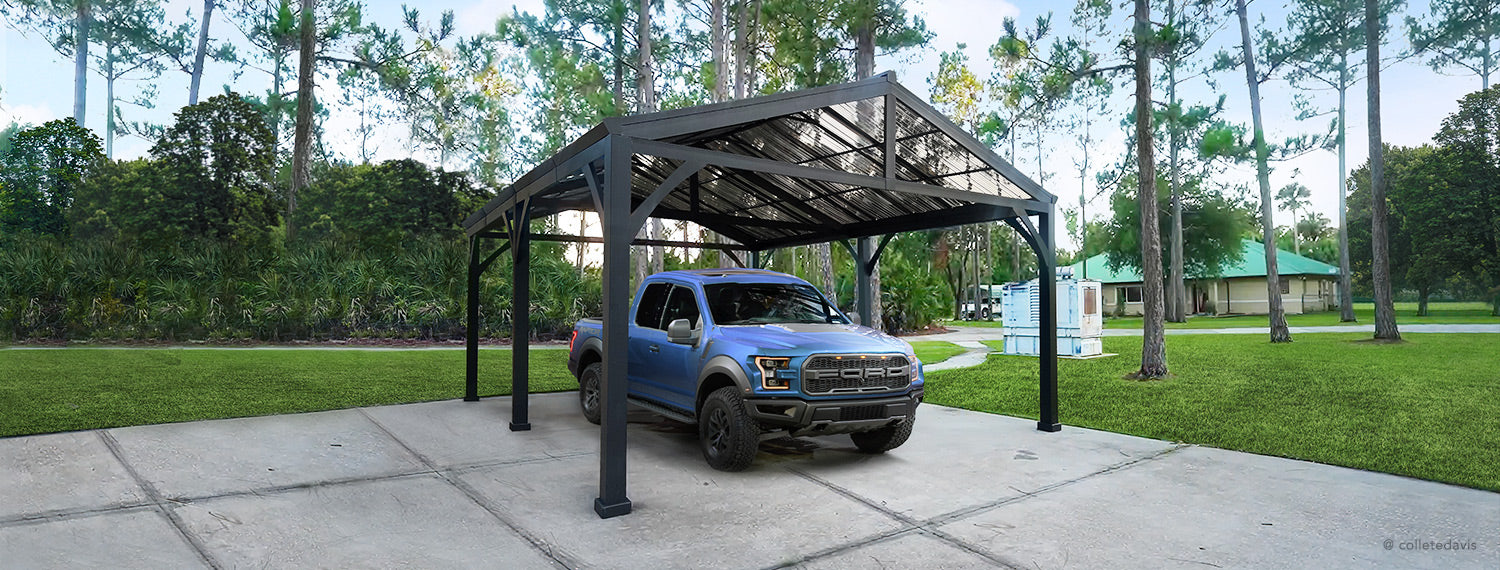
Three Comparative Insights That Will Change How You Buy a Carport

by Susan May 3, 2026
written by Susan

An on-site lesson and the numbers that followed

I was installing a 12×20 portable metal carport (model 8520) for a small business in Tel Aviv when a sudden storm exposed a pattern I had seen before — lightweight frames failing where anchoring was weak. Early in that day I checked car port for sale listings to compare specs and then recalled a March 2022 job where similar units lost panels; three failures out of ten — a 30% field failure rate (scenario + data) — so, do you track your wind load rating and anchoring system history before purchase? I say this plainly: I have removed low-grade units that looked fine on paper. I remember the client’s frustration — we reinstalled a galvanized steel replacement and saved roughly 25% of what repeated repairs would have cost (specific consequence). That experience taught me where traditional buying advice breaks down (a deeper layer): spec sheets ignore installation realities and local microclimate effects. Read on for a clear comparison of choices — and what matters most.

Carport

How resilient is your current enclosure?

When I inspect sites I look beyond price and surface finish. I check weld quality, bolt patterns, and whether the design accounts for local wind shear — terms like wind load rating, galvanized steel, and anchoring system are not marketing buzzwords for me; they are operational checks. I vividly recall June 2019 on Route 6 when a poorly anchored carport shifted and scratched three fleet vehicles — that cost was avoidable. You must measure: material grade, anchoring method, and on-site assembly tolerances. These three data points separate a durable carport from a recurring expense. This leads directly to the comparison I use with clients.

Carport

Direct comparison: what I choose and why

I will make a straightforward claim: not all “cheap” carports are worth the short-term savings. Over 15 years in B2B supply and on-site installation, I learned to weigh lifecycle cost over initial price. On a recent order for a municipal depot I insisted on a model rated for higher wind load and thicker galvanized coating — the client reported fewer corrosion incidents and no fastener failures after twelve months. That decision cut their total maintenance calls by nearly 40% (measurable result). If you are shopping for a car port for sale, compare rated wind loads, coating thickness, and attachment detail — not only footprint and color.

What’s Next?

I want you to leave with three practical evaluation metrics — simple, actionable, and backed by field work. First: wind load rating (documented figure for your postcode). Second: finish and material spec (galvanized steel thickness, clear numerical value). Third: anchoring system detail (mechanical anchor type and torque specs). I urge you to ask suppliers for test data — and if they cannot provide it, move on. I’ll interrupt myself — that’s non-negotiable. Also, visit an installed example nearby; seeing bolt patterns and seam welding in person tells you more than glossy photos. Finally, I recommend tracking one-year failure rates after purchase; measure, note, adjust. For reliable sourcing, consider established suppliers that publish specs and field reports — I trust brands that stand behind data. For practical procurement help, I often point buyers to SUNJOY.

May 3, 2026 0 comments
0 FacebookTwitterPinterestEmail
Business

Quiet Gains and Swift Credit: Revealing the Hidden Edge of DiDi Loans and Fast Online Credit

by Scott May 2, 2026
written by Scott

Comparative lead — two paths, one decision

The marketplace splits into urgent offers and steady tools; both promise speed, both whisper convenience. On one side: short-term online loans that push for instant approval. On the other: a structured credit product—think a didi card—that blends rewards with a credit line and predictable billing. This piece compares them with a focus on what really changes behavior in a city like Mexico City, where daily cash flow and commuting needs shape choices and risk tolerance.

The problem driving the comparison

Fast online loans often solve a single moment: a medical bill, a repair, a late rent. They’re underwritten quickly and delivered faster, sometimes within hours. The trade-off shows up as elevated interest rate and opaque fees. A credit card product, by contrast, spreads cost over time, offers revolving credit, and can include rewards that reduce net cost. The core issue is liquidity versus ongoing value—immediate relief versus cumulative benefit.

Practical differences that matter

Think in terms of three technical levers: APR and interest rate; credit line flexibility; and digital onboarding speed. Online loans typically present a fixed APR and a one-off repayment schedule. The card offers a revolving credit line and the option to carry balances with predictable minimums. Digital onboarding is rapid for both, but underwriting for a card might include more identity checks and fraud controls—slower at first, steadier afterward. These are not abstract terms; they change monthly cash flow and the true cost of borrowing.

Where rewards and savings hide

Hidden advantages accumulate. A card that gives cashback, transport credits, or discounts with partner merchants reduces effective expense. Over a year, modest monthly benefits beat a single small loan in many cases. Meanwhile, a short loan avoids compounding balances but can become expensive if rolled over. For urban workers who rely on a mobile wallet or regular commuting credits, the card’s benefits compound—small wins that change budgets in plain sight.

Real-world anchor: behavior during shocks

During the 2020 economic shock, many users in metropolitan areas converted ad-hoc borrowing into routine credit use; patterns shifted toward instruments that offered both access and control. That shift still matters: credit behavior hardened around products that combined digital convenience with ongoing incentives. This historical moment explains why some consumers prefer a managed credit product over an episodic payday loan—an observable change in market behavior rather than theory.

Common mistakes and small fixes

Borrowers often chase speed and miss cost. They accept the headline amount without mapping total repayment. They mix a high-interest loan with existing credit card debt—escalating risk. Fixes are simple: check APR, verify fees in writing, and compare the net value of rewards against the loan’s cost. Also, avoid juggling multiple short loans simultaneously—administration errors proliferate fast and interest compounds like a silent leak. —A short aside that matters to anyone managing multiple accounts.

How DiDi’s card fits the comparison

The tarjeta de credito didi positions itself as an alternative: digital onboarding, integrated rewards, and a clear billing cycle. For users who rely on repeat transactions—commuting, groceries, platform payments—the card turns routine spending into small rebates. For one-off emergencies, quick loans still have a role. The smart move is matching the tool to the task: liquidity needs meet short loans; ongoing spending meets a rewards card with responsible credit management.

Advisory close — three golden evaluation metrics

1) Total Cost: always calculate total repayment including fees and APR, not just monthly minimums. 2) Cash Flow Impact: model payment timing against your payroll schedule—pick the instrument that minimizes missed payments. 3) Net Benefit: quantify rewards or cashback over 6–12 months and subtract that from loan costs to see the real advantage. Use these metrics to decide quickly and precisely.

Final thought: small, steady advantages beat flashy speed when your month repeats. DiDi Finanzas often appears as the sensible bridge between instant relief and cumulative value—practical, measurable, quietly useful. –

May 2, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

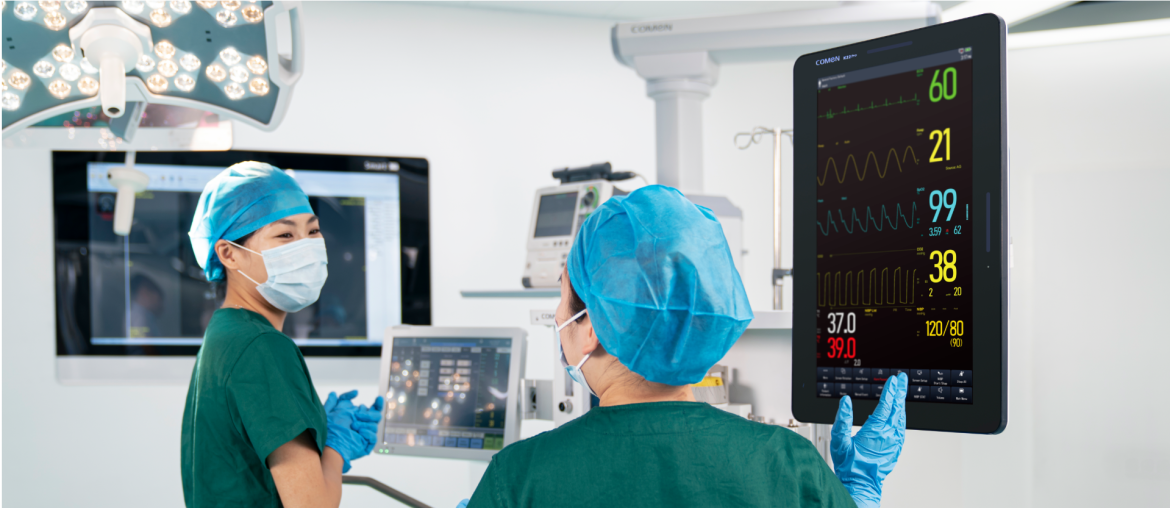
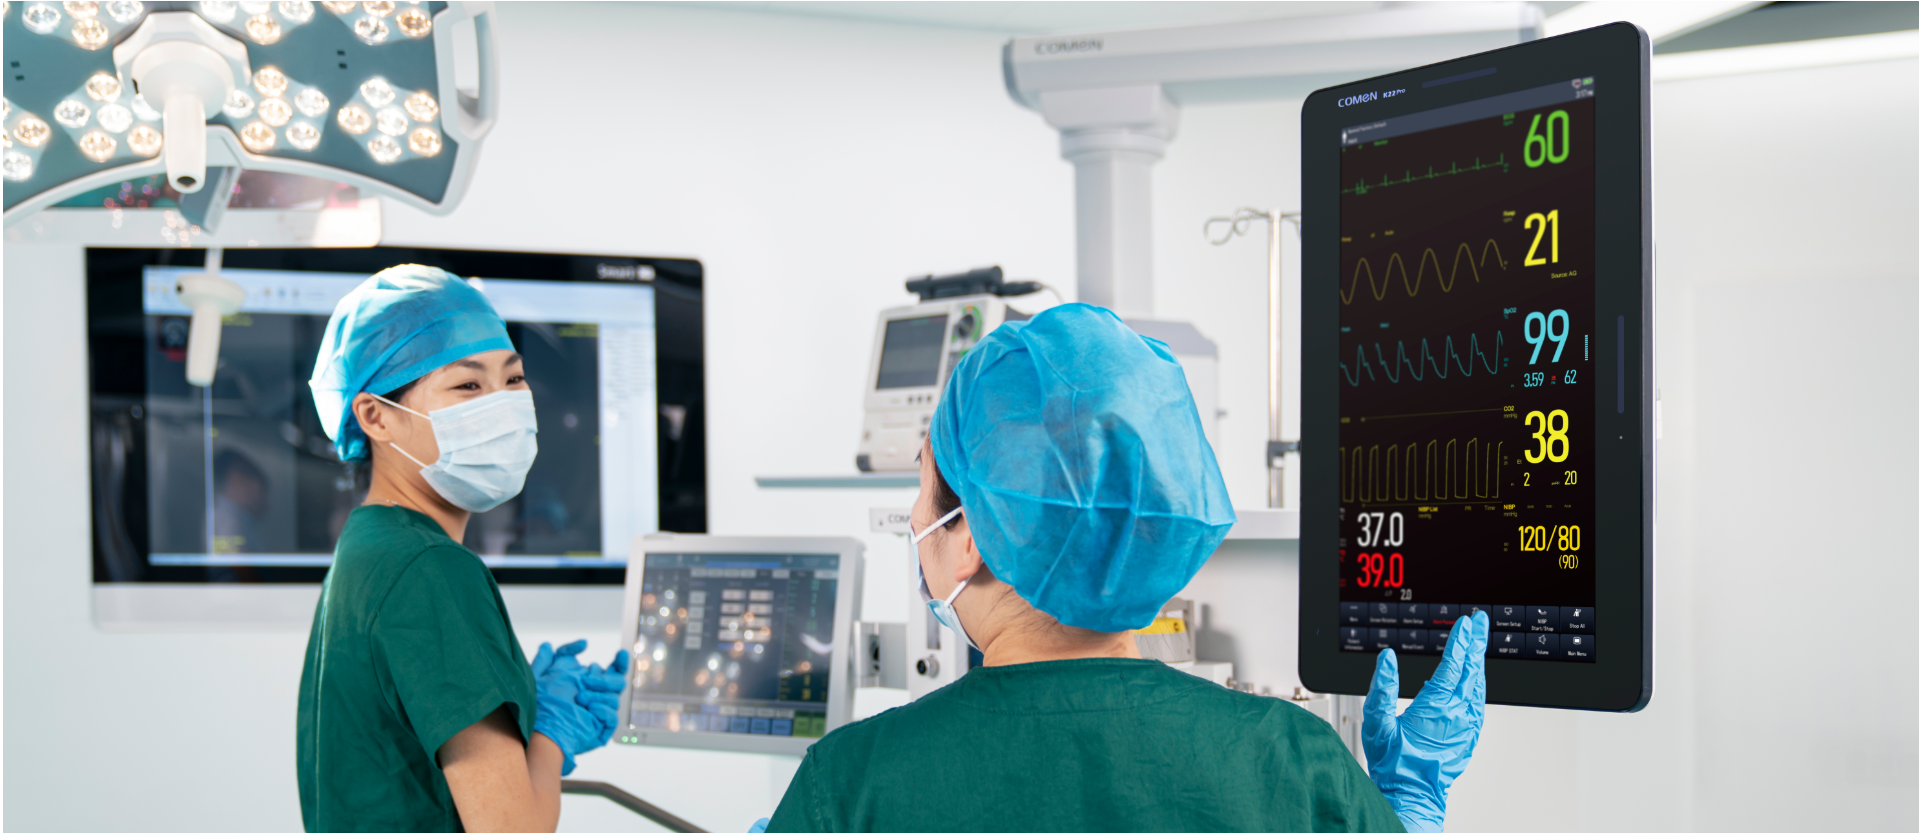
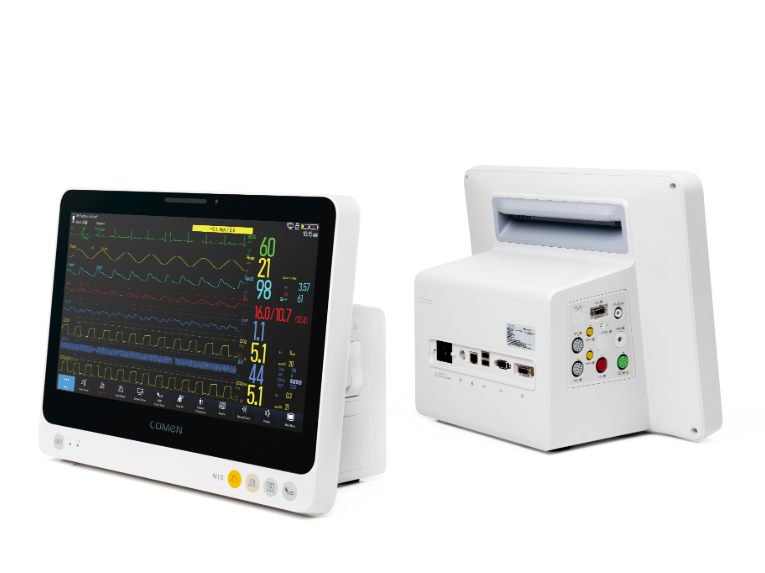
7 Practical Fixes for Patient Monitor Workflow Bottlenecks

by Kathleen May 2, 2026
written by Kathleen

Why the hospital floor still loses time to monitors

I once watched a nurse at St Vincent’s Hospital in Sydney spend 20 minutes reconciling a bedside multi-parameter monitor with notes — that stuck with me. Early on I learned that a lot of the pain around a hospital vital monitor isn’t the hardware; it’s the workflow and expectations. The patient monitor would show an ECG lead-off, SpO2 drop, then NIBP cuff error in quick succession — chaos. Scenario: a busy ward, data: 12 alarm events per patient-hour, question: how do we cut that down without risking care? (No jargon fluff — just the facts.)

patient monitor

I’ve been buying, testing and troubleshooting monitors for over 15 years and I still wince at designs that make nurses toggle through five menus to silence an alarm. I remember in March 2023 a procurement trial where a small UI tweak reduced alarm acknowledgement time by 28% on a demo bay — real numbers, real shift change impact. The traditional fixes—bigger screens, louder beeps—miss deeper flaws: poor telemetry integration, inconsistent waveform displays, and mismatched default alarm thresholds. I’m blunt about this because we wasted budgets on “upgrades” that didn’t address those core problems. And yes, it frustrated clinicians — no worries, mate — but it taught me where to push for change. This leads straight into practical next steps.

patient monitor

Fixes that actually change outcomes — and how to measure them

What’s Next?

Investing in better monitors is not a magic bullet; it’s a targeted effort (and it pays off). I’m confident that the right choices—better telemetry compatibility, configurable alarm tiers, clearer ECG and SpO2 waveforms—reduce nurse cognitive load and cut false alarms. Start by insisting on interoperability: I made that non-negotiable after a three-week rollout in a Sydney ward where systems failed to share NIBP trends — costly and avoidable. Next, insist on role-based default settings that match your unit (ICU vs general ward) so clinicians don’t fight the device during a crisis. Finally, demand data export and analytics; if you can’t pull alarm frequency and response times from the device, you can’t measure improvement — simple as that. In procurement discussions we pressed vendors for firmware logs and got them — which revealed a firmware bug that caused heartbeat duplication — fixed it, and reduced alarm noise. These are concrete wins; you can replicate them.

Three metrics to choose the right solution

I’ll leave you with three practical metrics I use when evaluating monitors: 1) Alarm fidelity — percentage of clinically relevant alarms versus false positives (aim for >70% relevance), 2) Integration latency — how quickly waveform and NIBP data appear in your EMR/telemetry stream (under 2 seconds ideal), and 3) Usability score from on-floor clinicians — a short 5-item survey after a 48-hour trial. I trust these numbers because I’ve used them in tenders and they separated good from useless. If you want a vendor that understands the reality of wards and the tech — check device fit, test in-situ, insist on training and ongoing support. I’ve done the hard yards, negotiated contracts, sat through firmware calls — and I still back those three checks. For practical supplies and reliable units, see COMEN — they know the ropes and will talk real specs, not sales blurbs.

May 2, 2026 0 comments
0 FacebookTwitterPinterestEmail
Global Trade

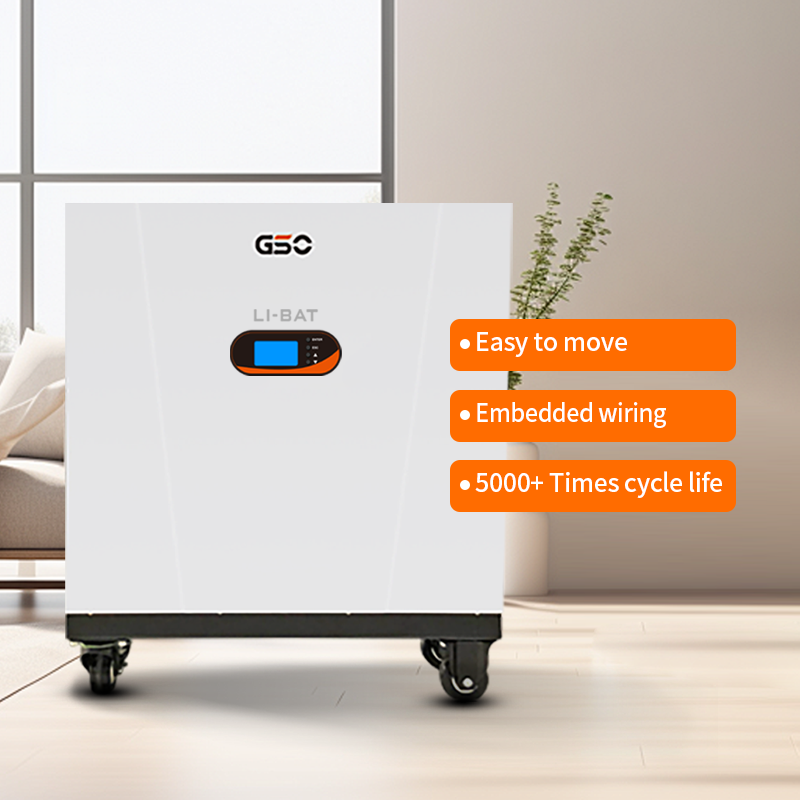
The Anatomy of an Uninterruptible Micro-Grid: Reimagining High-Surge All-in-One Storage

by Rachel April 29, 2026
written by Rachel

Problem: The Surge That Breaks Quiet Systems

When mains fail, the problem is rarely simple absence of power — it is the sudden demand: motors, pumps, medical devices that call for high surge power in the first seconds of restart. For many homes and small facilities, patchwork solutions fail at that instant. The practical answer increasingly sits in integrated units such as the Portable Solar Power Station, designed to deliver both sustained output and brief, high peak power without separate installs.

Portable Solar Power Station

Why All-in-One Storage Solves More Than Space

All-in-one systems combine inverter, battery, and control electronics into a single chassis, trimming installation time and the friction of coordinating multiple vendors. The primary technical aim is to provide clean, immediate power and robust surge capacity while remaining portable. For installers steeped in fieldwork, this reduces wiring mistakes and avoids mismatched inverter-battery chemistry — a common source of failures.

Core Elements That Decide Success

An effective unit balances three things: the inverter’s waveform fidelity, the chemistry’s durability (LiFePO4 is common for long cycle life), and a resilient battery management system (BMS) that protects against overcurrent and thermal drift. Surge capacity is not merely advertised watts; it is a combination of inverter design, short-term thermal handling, and battery discharge kinetics. A device may claim high peak power, yet lack the thermal headroom to sustain repeated surges — this is where real-world performance diverges from specs.

Field Anchor: Lessons from Extended Outages

After Hurricane Maria in Puerto Rico, long outages exposed differences between systems that simply floated in standby and those that supported heavy loads for extended periods. Community centers using thoughtfully specified all-in-one storage kept refrigeration and medical gear running through the worst weeks; smaller gear collapsed under the first major surge event. That episode clarified a basic truth: surge ratings and sustained runtime both matter — and they must be verified together.

Common Mistakes and Better Practice

Specifiers often focus only on capacity (kWh) and ignore peak power and thermal limits. Others skimp on ingress protection for outdoor installs. Expect to check the inverter’s continuous vs. surge ratings, confirm LiFePO4 cell specs if long life is required, and insist on a BMS with clear fault reporting. Avoid mixing brands for inverter and battery unless compatibility has been validated — mismatched communication protocols can leave devices blind to a fault. Small oversight, big consequence — that is the field lesson.

Comparisons and Alternatives

Pure battery banks tethered to separate inverters may offer flexibility but add complexity and potential points of failure. Portable solar batteries integrated with inverter hardware remove those gaps and simplify commissioning. For larger micro-grids, modular rack systems scale, but they demand stronger site design and, often, heavier civil works. Choose the form factor that fits maintenance capability as much as power needs.

Design Rules and Human Realities

Design is technical, yet decisions get made by humans under stress. Prioritize systems that provide simple status feedback, audible alarms, and easy swap procedures for field techs. Consider redundant critical circuits and plan for predictable maintenance windows. A compact, all-in-one unit can ease logistics when roads are blocked or staff are limited — the poetic consolation of practicality.

Portable Solar Power Station

Advisory: Three Golden Metrics for Selection

1) Surge-to-Continuous Ratio — measure the inverter’s surge watts against continuous watts and verify the number of allowable surge events per hour. This predicts behavior when motors or compressors cycle.

2) Run-Time per Kilogram — assess runtime relative to system weight for portability; higher energy density (with safe LiFePO4 chemistry) often wins field deployments where transport is limited.

3) BMS Transparency and Warranty Coverage — prefer systems with clear fault logs, remote monitoring options, and warranty terms that cover both cells and inverter electronics, because field costs are rarely just parts.

The synthesis of these metrics points naturally to integrated solutions that blend inverter quality, cell chemistry, and control logic — a role well served by products from gsopower. —

April 29, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Practical Framework for Balancing State of Charge and Depth of Discharge in Commercial Battery Fleets

by Nicole April 28, 2026
written by Nicole

Opening: why a framework helps you act with confidence

Deploying a commercial battery fleet without a repeatable playbook is risky — you end up guessing SoC windows and DoD limits in the field. This short framework gives engineers and ops managers a stepwise way to set, monitor, and revise those parameters. If you’re sizing reserve margins, coordinating grid services, or planning maintenance windows, the guidance below scales from a single site to utility scale battery storage deployments and helps minimize surprises in performance or cost.

utility scale battery storage

Core concepts: SoC, DoD, and related terms

Keep the definitions simple. State of Charge (SoC) is the battery’s current stored energy as a percentage of its usable capacity. Depth of Discharge (DoD) is how much capacity you’ve used since full charge. Other useful terms to track are cycle life, round-trip efficiency, battery management system (BMS), and capacity fade. These terms guide operational choices — for instance, higher DoD typically shortens cycle life and accelerates capacity fade, while tight SoC windows can improve longevity but reduce usable energy for services.

Why fleet-level optimization matters (real-world anchor)

One rooftop or microgrid behaves differently than a fleet managed across regions. Look at Hornsdale Power Reserve in South Australia: coordinated operations there demonstrated that optimized charge windows improve dispatch reliability during peak demand. Likewise, California’s grid events have pushed operators to tune SoC setpoints to balance reserve readiness against battery aging. Fleet-level thinking turns device-level rules into coordinated outcomes across time zones and market signals.

Framework overview: four operational layers

Think in four layers you can implement in sequence:

  • Policy layer — business rules for reserve, arbitrage, and lifespan targets.
  • Planning layer — capacity, expected cycles per year, and degradation models.
  • Control layer — BMS setpoints, SoC limits, and charge/discharge rate caps.
  • Monitoring layer — telemetry, alarms, and automated adjustments tied to SCADA or EMS.

Each layer feeds the next: policy defines targets, planning translates targets into SoC/DoD bands, control enforces them, and monitoring closes the loop.

Step 1 — Define mission profiles and acceptable degradation

Start by categorizing each asset by primary mission: capacity firming, frequency response, energy arbitrage, or backup. For example, frequency response needs fast power but shallow cycles; backup wants higher reserve SoC. Translate mission into acceptable annual energy throughput and calendar life targets. Use a simple degradation model to estimate capacity fade under different DoD distributions — this converts abstract targets into concrete SoC/DoD trade-offs.

Step 2 — Set pragmatic SoC windows and DoD rules

Set SoC windows that balance availability and longevity. A conservative default might be 20–80% SoC for daily-rated assets, which limits DoD and extends cycle life. For assets providing bulk energy, a wider window (5–95%) may be justified if you accept faster capacity fade. Tag each site with a certified SoC band and an emergency override rule for extreme events. Don’t forget to account for round-trip efficiency when modeling energy available for market services.

Step 3 — Implement BMS policies and fleet orchestration

Translate your SoC/DoD rules into BMS parameters and fleet-level orchestration logic. The BMS enforces cell-level safety while the fleet EMS schedules dispatch across sites to meet policy targets. When linking to market signals or contingency reserves, use dynamic SoC setpoints that respond to price or grid alerts — but cap dynamic excursions to avoid frequent deep cycles. Integrating with proven grid scale energy storage systems architectures reduces engineering lift and standardizes telemetry streams.

Step 4 — Monitor, learn, and adapt

Continuous monitoring closes the loop. Track charge/discharge profiles, cycle counts, voltage spread, and temperature. Compare observed capacity fade against your model quarterly and adjust SoC/DoD windows if actual degradation deviates. Automated alerts should trigger when individual units hit pre-set cycle thresholds or when fleet reserve margins fall below policy limits — this keeps human intervention focused on exceptions, not routine adjustments.

Common mistakes and how to avoid them

Operators often fall into three traps: over-optimistic usable capacity, ignoring ambient temperature effects, and relying on static SoC setpoints. Overestimating usable capacity causes missed service obligations. Temperature accelerates capacity fade — so environmental controls matter. And static setpoints ignore market and grid volatility — dynamic policies are better, though they must include hard limits to prevent chronic deep discharge. —

Practical checks before go-live

Run these checks as a minimum before commercial operation:

  • First-article test: show your BMS holds SoC windows under all expected charge rates.
  • Simulated year: run one-year dispatch scenarios to expose frequent deep cycles.
  • Fail-safe validation: confirm the fleet can meet minimum reserve requirements during communications loss.

Three golden rules for evaluating SoC/DoD strategies

1) Measure outcomes, not intentions: track delivered MWh vs. projected MWh and adjust policies when cumulative deviation exceeds tolerance. 2) Prioritize service-driven limits: let mission profiles dictate SoC windows rather than arbitrary percentiles. 3) Insist on telemetry fidelity: precise SoC, cycle counts, and temperature logs are non-negotiable for trustworthy lifecycle forecasts.

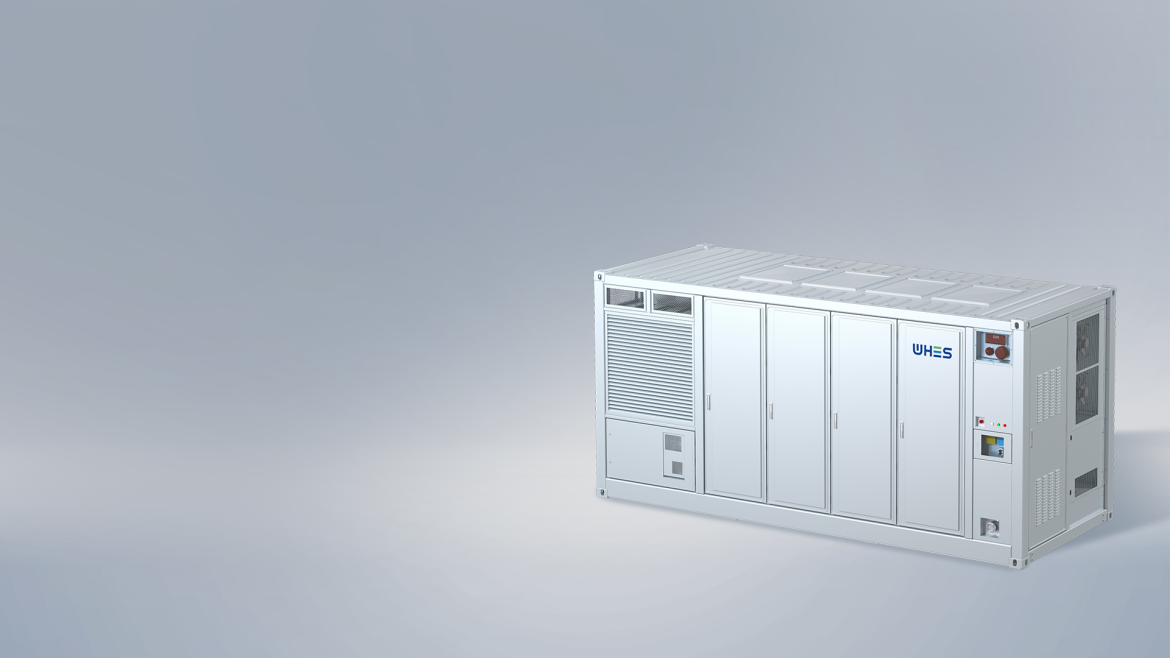
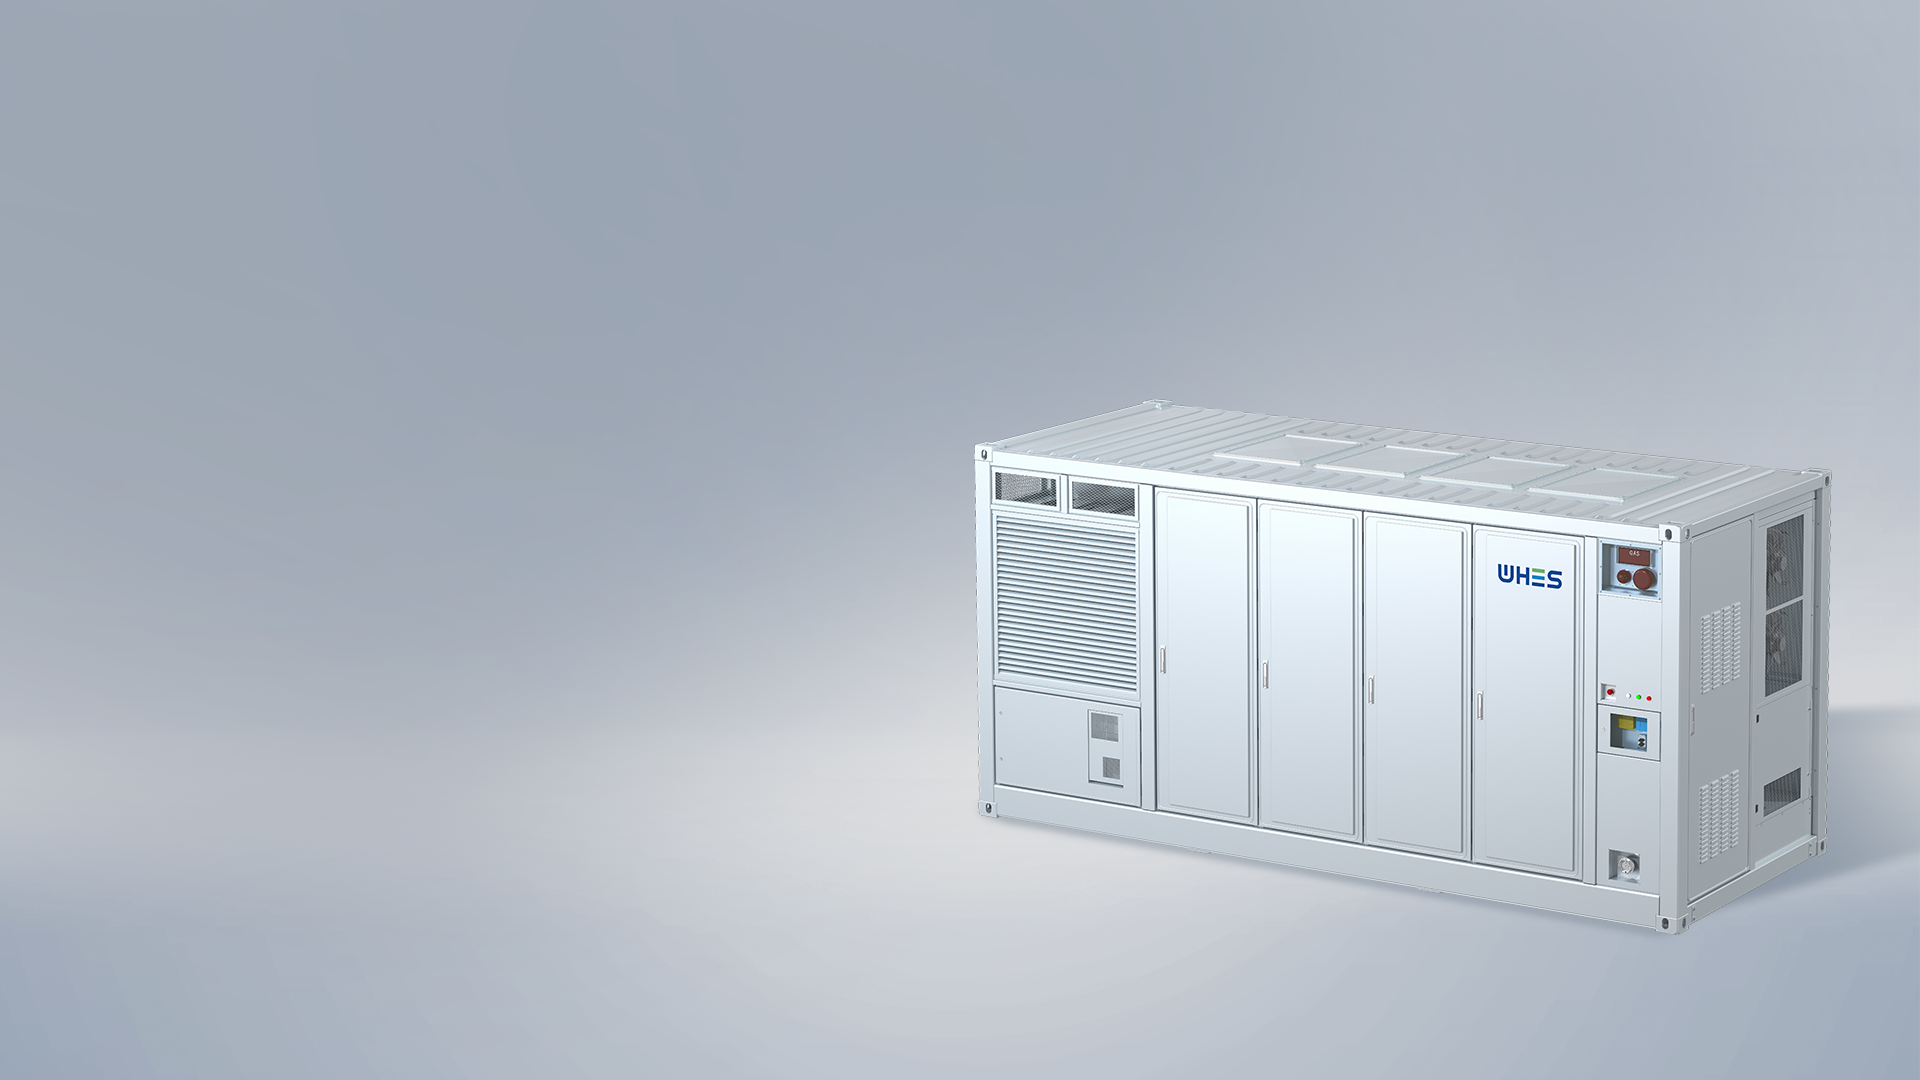
These rules help you pick strategies and vendors that marry operational reliability with realistic lifetime expectations. For fleet deployments that must balance market participation and durability, a standardized, tested architecture saves months of engineering and simplifies O&M — and that’s where seasoned platform providers matter. WHES. —

April 28, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Mastering Quality Enhancement in Abs Plastic Injection Molding

by Debra April 28, 2026
written by Debra

Understanding the Challenges

Have you ever wrestled with product defects that drive you crazy? Around 30% of plastic parts fail quality inspections, a staggering statistic in today’s manufacturing landscape. As an abs plastic injection molding manufacturer, I know all too well the implications of these failures on operational costs and customer satisfaction. Here, we delve into the common pitfalls of traditional processes that often leave manufacturers struggling to maintain quality. It’s not just about meeting standards; it’s about developing a culture that prioritizes excellence.

abs plastic injection molding​

Common Flaws in Traditional Solutions

Many manufacturers opt for shortcuts that compromise the integrity of their products. Take, for example, the frequent reliance on outdated quality checks. These methods might seem effective at first glance, but they hide serious risks. One time, I was involved with a plant that depended solely on visual inspections. We learned the hard way that this led to consistent discrepancies in molding accuracy, jeopardizing client relationships. It’s crucial to move beyond superficial assessments.

What Are the Hidden Pains?

Hidden pain points also lurk in the corners of a factory. Inadequate training on equipment, for instance, leads to operational inefficiencies. I’ve encountered workshops where staff was left to figure things out on their own, resulting in wasted materials and time. If the team isn’t equipped with the necessary skills and knowledge, faults in production become inevitable. Networking within industry circles helped me identify resources that can bolster training efforts effectively.

What’s on the Horizon for Quality Control?

Moving forward, manufacturers must adopt a more proactive approach, utilizing technology to enhance quality control measures. Implementing real-time monitoring through IoT Can make a substantial difference in identifying defects early. The cost-benefit analysis showed that companies embracing such innovations improve their production line efficiency by up to 40%. As an abs plastic injection molding manufacturer, this shift is essential for staying competitive.

abs plastic injection molding​

Evaluating New Tools: What Should You Consider?

When exploring new methods for quality enhancement, I suggest focusing on three key evaluation metrics: accuracy, reliability, and consistency. These factors will determine the long-term success of any solutions you implement. Adopting a holistic view also means collaborating with advanced suppliers—like honing relationships with companies that specialize in innovative technologies, which can drastically streamline processes.

Lessons Well Learned

In conclusion, my years in this industry have taught me one vital lesson: the quest for quality is never-ending. Implementing the right tools can lead to transformative results—a well-oiled production machine that doesn’t just meet quality standards but exceeds expectations. When manufacturers pay attention to the details, they cultivate loyalty and trust among their clients.

So, don’t rely on outdated processes—explore and invest in what’s ahead. Consistent quality is a game-changer, commensurate with hard work and forward-thinking strategies. Visit Livepoint Mould for insights into how you can enhance your production capabilities and foster unparalleled quality in your plastic injection molding processes.

April 28, 2026 0 comments
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • What to Ask When Shortlisting Plastic Junction Box Options?
  • How to Pick the Best Lighting for Your Fish Aquarium — A User-Focused Guide
  • A Practical Procurement Checklist for Brackish Membrane Projects
  • 4 current transducer in 2026
  • Evaluating Suppliers of Single-Basin Kitchen Sinks: A Problem-Driven Checklist

Recent Comments

No comments to show.

Keep in touch

Facebook Twitter Instagram Pinterest Behance Youtube Tiktok

Taxonomy Listing

Business

Decorate

DIY Projects

Expert Advice

Gardening

Global Trade

@decor.joy3?lang=en

Follow us @ashlynn on Instagram and TikTok!

Categories

    • Archdaily
    • Specification
    • Building
    • Competition
    • Design
    • Consetvation
    • Architecture
    • Feature
Facebook-f Youtube Tiktok Instagram Pinterest-p

u00a92025 Soledadu00a0All Right Reserved. Designed and Developed byu00a0Penci Design

Send daily email

bestweb345
  • Home
  • Decorate
  • Gardening
  • House Tours
  • DIY Projects
  • Expert Advice
  • More