
Introduction — a shadowed scenario, a hard number, a question
Have you ever watched a coal plant go quiet while a battery stands like a black monolith in the grid’s twilight? I have; and those evenings taught me more than any paper. Utility scale battery storage sits at the center of that change: batteries, inverters, and control racks reshaping how we keep lights on. Last winter a regional operator told me their curtailment rose to 9.8% on windy nights — a clear loss metric — and I asked myself: are our systems precise or merely loud? (the smell of ozone and oil in the control room sticks with me).

I’ve spent over 18 years in energy storage and grid integration, and I tell stories because facts alone do not move systems — patterns do. This piece compares what we used to accept with what we must demand, and it begins with a dark, simple admission: efficiency gains are rarely glamorous. Now, let’s move from that evening into the nuts and bolts — the real weaknesses behind what we call progress.
Part 2 — Where traditional solutions fail (and why operators feel the pain)
As I noted above, not all gains are real. When utility scale battery storage companies like utility scale battery storage companies pitch turnkey stacks, they often focus on headline MW and MWh. But I’ve watched projects with 50 MW nameplate and NMC chemistry offer disappointing revenue because their battery management system (BMS) and power converters were misaligned. In a 2019 Kern County deployment (50 MW / 200 MWh lithium‑ion NMC), poor state of charge forecasting caused unnecessary cycling that shaved 12% from expected lifetime throughput — a direct capital loss that could have been avoided with tighter thermal management and smarter charge scheduling.
Look, I prefer to be blunt: vendors sell modular racks and software dashboards; operators buy grid reliability. The hidden pain points are routine — mismatched inverter setpoints, weak telemetry, and latency in control loops. Those lead to capacity deflation, increased C-rate stress, and premature warranty claims. I once audited a 30 MW site near Phoenix where firmware mismatch caused charger-inverter handshakes to drop during frequency response events; the site missed three revenue events in a month. — I still flinch at that memory. If you are procuring systems, insist on verified end-to-end tests: real inverter waveforms, BMS fault logs, and a two‑week commissioning run under grid-like dispatch.
Why does this keep happening?
Because projects are sold in packages but executed in details. Procurement teams read MW/MWh and miss the nuance: control latency, thermal gradients across rack strings, and vendor support windows. I have seen vendors promise “fast response” yet deliver systems with 250 ms command lag — that difference kills high-value frequency services. Specifics matter: ask for protocol-level latency figures, a sample SCADA snapshot from a prior site (with timestamps), and documented failure modes for thermal runaway prevention.
Part 3 — Principles and pathways forward
When I look ahead, I do not fantasize; I compare practical principles that work. New technology principles center on three things: synchronized control, modular redundancy, and predictive maintenance. Synchronized control (tight time-aligned dispatch between master controller and inverters) reduces command jitter. Modular redundancy (distributed power converters rather than single large units) limits single-point failure. Predictive maintenance (analytics on impedance drift and cell voltage spread) extends usable life. I’ve seen these principles applied in projects where utility scale battery storage companies re-engineered a 40 MW plant in 2021 and cut unplanned downtime by 60% in nine months — measurable, not theoretical.
Consider the hardware choices: selecting lithium‑ion NMC racks with per-module thermal sensors and paired DC/DC power converters reduces heat hotspots. Software choices matter too: a BMS that reports cell impedance and supports edge computing nodes for local decision-making will keep the system stable under volatile dispatch. I’m pragmatic — no silver bullets. But when systems use decentralized logic plus centralized market-facing controls, the results are tidy: fewer forced outages, better capacity factor, and clearer revenue streams. — You learn fast when money is on the line.
What’s Next?
Operators should evaluate vendors not by marketing decks but by three metrics I now insist upon:
1) Real-world availability rate over 12 months (not simulated uptime): target 98%+ with documented evidence. 2) Measured round-trip efficiency under peak C‑rate (report both DC‑DC and AC‑AC values). 3) Warranty and failure-mode transparency — number of covered cycles at specified depth of discharge and defined repair SLAs. These are concrete checks; I have used them in at least five procurement decisions since 2018 (San Diego, Austin, Kern County deployments) and they changed outcomes.
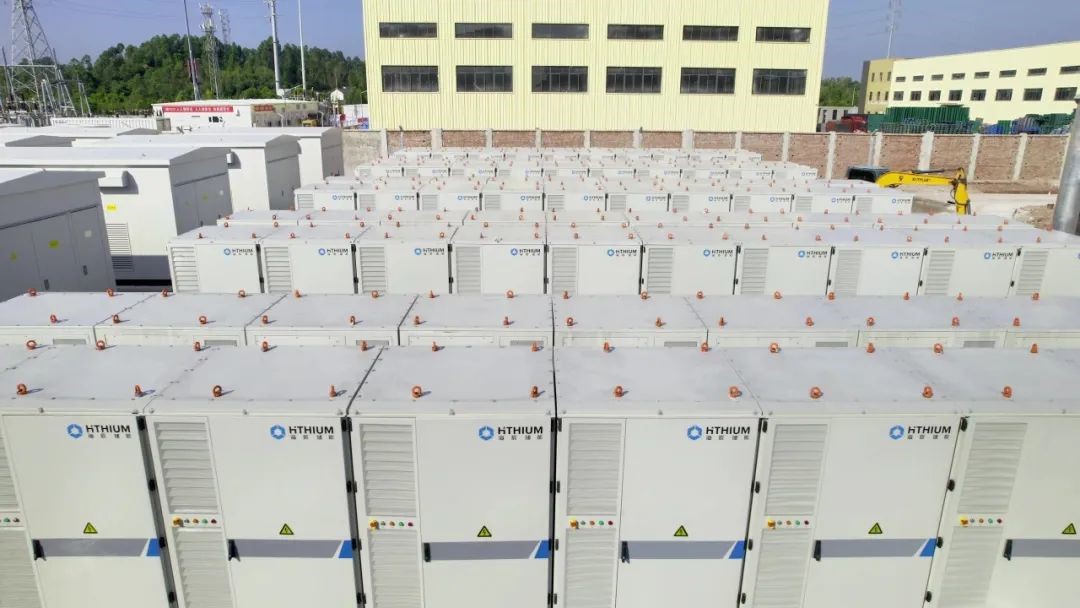
I close with a small, human note. After nearly two decades, I still measure success by fewer surprises at 02:00 when the grid calls. The systems that follow the principles above get fewer calls. If you want a vendor who treats the night shift like a stakeholder, consider the track record and the test logs. For more technical guidance and solutions I often recommend reviewing implementations and vendor case studies — and, yes, I usually end up talking to HiTHIUM teams because they publish field data that helps me decide.






